September 18, 2026
From GPT-3 to GPT-5: How AI translation quality actually changed
GPT-3, GPT-4, and GPT-5 are five years and several architecture generations apart, but the useful question for translation isn't "which one is smartest." It's narrower: what specifically changed in how these models handle the parts of a language that don't translate word for word, things like idioms, ambiguity, and register? The improvement happened in specific places, at specific points, and it didn't run in a straight line from older to newer.
What GPT-3 actually offered for translation
OpenAI released GPT-3 in 2020, before MachineTranslation.com's own testing program existed, so nothing here is a proprietary benchmark. It's well-documented history, not an internal test result. GPT-3 was the first model of its kind capable of producing fluent, human-sounding text in multiple languages without task-specific training, which made it a genuine milestone. For translation specifically, that same fluency created a real risk: GPT-3 could produce a confident, well-formed sentence in the target language that was still wrong, with nothing about the output signaling that a mistake had occurred.
What changed when GPT-4 arrived
GPT-4 launched in March 2023, and MachineTranslation.com's own model testing picks up around this generation. The improvement was real but uneven. Testing the ambiguous English phrase "That's sick" in Japanese, GPT-4.1-nano was the only model of six tested that collapsed the line's deliberate double meaning into a single interpretation, where the other five preserved the ambiguity the original phrase intended. Idioms were a bigger weakness: running the Spanish idiom "llevarse el gato al agua" through five GPT versions at once, the smaller GPT-4o-mini and GPT-4.1-nano both produced the same literal, incorrect translation, missing the idiom entirely.
The same pattern showed up elsewhere. A German idiom, "ich verstehe nur Bahnhof," run through eight GPT and Claude sub-versions, was translated literally and incorrectly by GPT-4o-mini specifically, while a smaller, newer model in the same test, GPT-4.1-nano, got it right. Generation and model size did not correspond in any consistent way, a pattern MachineTranslation.com's model-version testing covers in more depth.
What GPT-5 changed for translation
OpenAI introduced GPT-5 as a unified system that routes between a fast default model and a deeper reasoning model depending on the task, a structural change from GPT-4's single-model design. OpenAI's own GPT-5 System Card reports the model's overall factual error rate at roughly 45% lower than GPT-4's and 80% lower than GPT-3's, a general reliability gain that shows up specifically for translation too. MachineTranslation.com's testing shows the clearest gains where GPT-4-era models struggled most: on the same Spanish idiom that GPT-4o-mini and GPT-4.1-nano got wrong, both GPT-5.4-mini and GPT-5.4 landed on correct, idiomatic translations, each phrasing it slightly differently but both understanding the idiom itself.
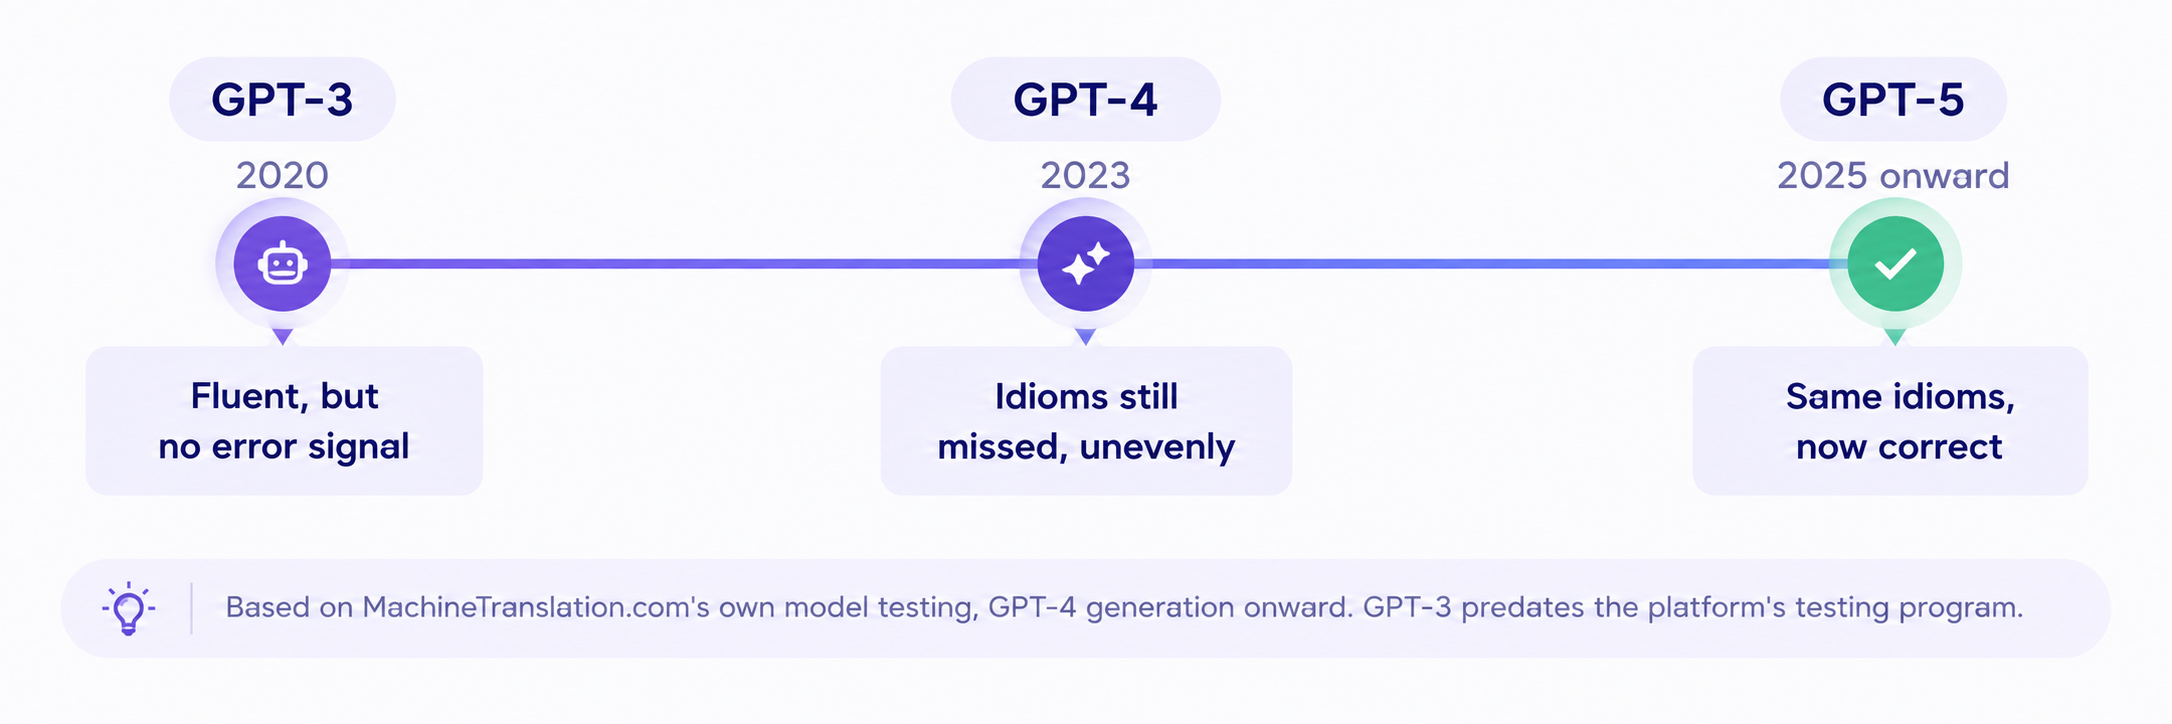
The gap between generations wasn't a steady climb. It was concentrated almost entirely in idiomatic and ambiguous language. On straightforward text, GPT-4-era and GPT-5-era models score close to identically.
| GPT-3 | GPT-4 | GPT-5 | |
|---|---|---|---|
| Released | 2020 | March 2023 | 2025, now on GPT-5.4/5.5 |
| Available today | No, retired | API only, retired from ChatGPT | Yes, current generation |
| Idiom handling | Not tested by MachineTranslation.com (predates program) | Inconsistent; missed several idioms outright | Correctly handled the same idioms GPT-4 missed |
| Standard business text | Not tested by MachineTranslation.com | Strong, near-identical to later models | Strong, near-identical to GPT-4 |
That last point matters: a separate test of a standard business phrase, "please confirm receipt of this document," translated into German, returned near-identical output across every model tested, GPT-4o-mini and GPT-5-generation models included. The generational gap is specific to figurative and ambiguous language, not a blanket quality difference.
Does a newer GPT generation always mean better translation?
No. Testing a Hebrew idiom across model families, GPT-5.4-mini and GPT-5.4 landed on two different, partial interpretations of the same phrase, neither one fully correct, while an older, unrelated model got closer. A newer model is not automatically a more accurate one, and a bigger or more recent model is not automatically the safer choice for a given sentence.
Where GPT-5 stands for translation today
GPT-3 and GPT-4 are both retired from ChatGPT; GPT-4 remains reachable only through OpenAI's API for existing integrations. The current generation, GPT-5.4 and GPT-5.5, is what MachineTranslation.com runs today, and it performs competitively against current models from other providers, though not uniformly better on every language pair. For a closer look at how current GPT sub-versions compare against each other and against models like Claude and DeepSeek, see MachineTranslation.com's head-to-head sub-version testing, which goes deeper than a generational overview can.
What this means if you're localizing at scale
The finding that matters most for a large localization program isn't "GPT-5 beats GPT-3." It's that model version, not just model family, determines whether a specific idiom or ambiguous phrase gets translated correctly, and that holds true across every language pair, not just the handful shown here. This matters most in content that leans on tone and figurative language in the first place, marketing copy and user-generated content especially, where a single idiom translated literally can change the whole meaning of a post or an ad. A program moving content into dozens of languages will hit exactly this kind of language in every one of them. MachineTranslation.com's sub-version testing series and full model comparison testing cover this in more depth. The platform's approach, running current GPT models alongside more than 20 others on every translation, exists specifically because no single model's version history is a reliable enough guarantee on its own.
Frequently asked questions
1. What's the real difference between GPT-3, GPT-4, and GPT-5 for translation?
GPT-3 handled straightforward text reasonably well but struggled badly with anything idiomatic or ambiguous. GPT-4 narrowed that gap significantly but still collapsed some genuinely ambiguous phrases into a single meaning instead of preserving the ambiguity. GPT-5's later sub-versions correctly handled idioms that earlier GPT-4-era models translated literally and wrong.
2. Is GPT-5 always better than GPT-4 at translation?
No. MachineTranslation.com's own testing has found cases where a smaller, newer sub-version outperformed a larger, older one, and the quality gap between generations tends to be specific to idiomatic or figurative language rather than a general, across-the-board improvement.
3. Does OpenAI still offer GPT-3 or GPT-4?
No. Both have been retired from ChatGPT and replaced by newer GPT-5-generation models. GPT-4 remains accessible only through OpenAI's API for existing integrations, not as a current consumer-facing option.
4. Which GPT version does MachineTranslation.com use?
MachineTranslation.com runs current GPT-5-generation models (GPT-5.4 and GPT-5.5, depending on plan tier) alongside more than 20 other AI models on every translation, rather than relying on GPT alone.
5. How does GPT-5 compare to other current AI models for translation?
GPT-5-generation models perform competitively but not uniformly better than models like Claude, Gemini, or DeepSeek. Different models win on different language pairs and content types, which is why MachineTranslation.com tests them against each other directly rather than picking one as a default.
By Rachelle Garcia
Connect on LinkedInRachelle leads product and AI at Tomedes, where she runs the experiments that turn internal data into better translation experiences. She writes about what actually happens when you build AI products such as MachineTranslation.com — the numbers, the surprises, and the parts that don't go to plan.
Share:


