September 9, 2026
Qwen vs DeepSeek: Which AI model translates better?
Run the same 12,000 translation segments through Qwen and DeepSeek, and DeepSeek wins the majority of language pairs. That's not the whole story. Split the results by direction, and a specific pattern shows up: Qwen closes most of the gap, and sometimes takes the lead, specifically when the target language is English. Translating out of English into anything else, DeepSeek wins almost every time.
That split matters more than a single overall winner if you're translating content across dozens of languages rather than one language pair.
What are Qwen and DeepSeek?
Qwen is Alibaba's family of large language models. The current generation is Qwen3.8, released in August 2026: Qwen3.8-Max is the closed, API-only flagship at 2.4 trillion parameters, while Qwen3.8-27B is a smaller, open-weight model released under Apache 2.0 a few days later, aimed at teams that want to self-host.
DeepSeek is a Chinese AI lab known for mixture-of-experts models that match frontier performance at a fraction of the inference cost. Its current generation, DeepSeek V4, launched in April 2026 in two variants: V4 Pro (1.6 trillion total parameters, about 49 billion active per token) for quality-focused work, and V4 Flash (284 billion total, about 13 billion active) for latency-sensitive workloads. Both ship as MIT-licensed open weights.
How do Qwen and DeepSeek actually compare on translation, not just benchmarks?
Most Qwen vs DeepSeek comparisons cite general-purpose benchmarks: coding, math, reasoning. None of those measure translation quality directly, and running each model on different source text makes any accuracy gap impossible to isolate from what the text itself demanded.
MachineTranslation.com's own translation traffic over the last 28 days gives a cleaner answer, because both models translated the identical source text. Across 98 language pairs and more than 12,000 matched segments, DeepSeek scored higher in 83 pairs; Qwen scored higher in 15. Narrow that down to the 27 pairs where the target language is English, and the gap shrinks sharply: DeepSeek wins 63% of them (17 of 27), Qwen wins 37% (10 of 27). Across the remaining 71 pairs, where English isn't the target, DeepSeek wins 92% (66 of 71).
Win rate by translation direction (98 language pairs, identical text)
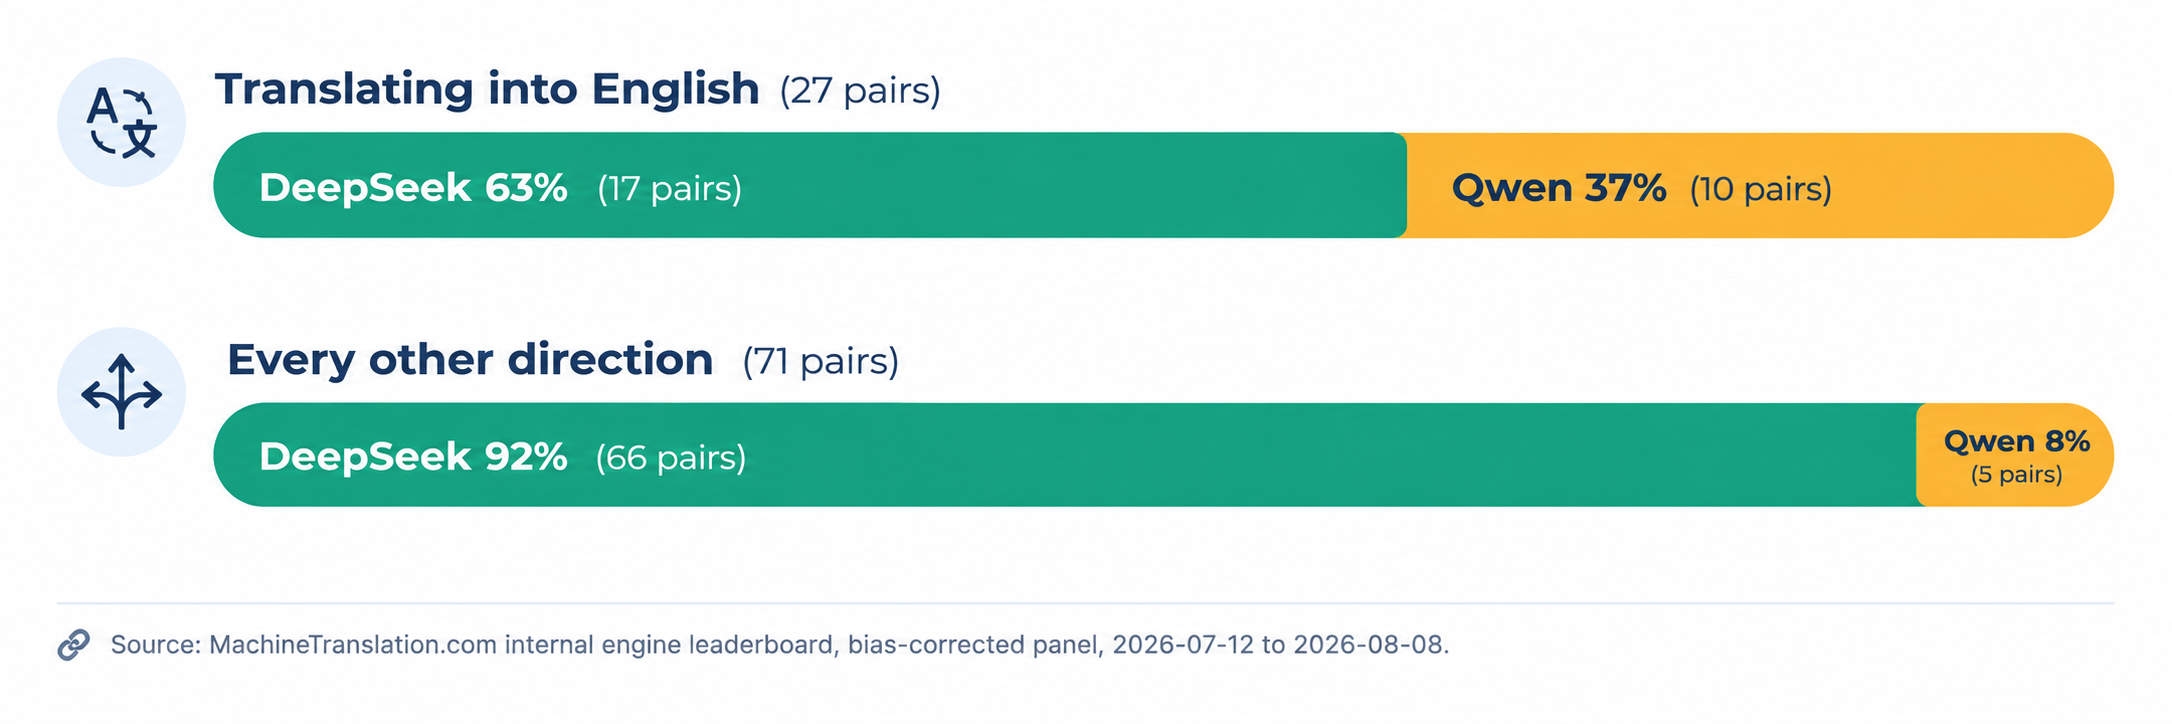
DeepSeek wins the large majority of language pairs overall. Qwen's competitive window is narrow but real: translating into English, where it takes more than a third of pairs. Data: MachineTranslation.com's internal engine leaderboard, bias-corrected panel, July 12 to August 8, 2026.
The weighted average across every matched segment puts DeepSeek at 9.13 out of 10 and Qwen at 8.98. That's a real gap, but it's not evenly distributed, which is the more useful thing to know if your content moves in more than one direction. This is the same head-to-head approach MachineTranslation.com uses across its full model comparison testing, not just for this one pair.
The aggregate numbers hold up in individual test cases, too. Testing the French phrase "Elle est directrice adjointe du département commercial," DeepSeek and Qwen converged on the same English rendering, "deputy director of commercial department". You can check that live test result directly. Testing "as soon as possible" translated into Spanish, DeepSeek broke from the four-model consensus with "esté hecho" instead of "se haga" which is a real divergence case that reflects a process-versus-outcome grammatical distinction, not a mistake.
Why does Qwen do better translating into English specifically?
The data doesn't explain why, only where. Some of Qwen's strongest into-English pairs are Tamil, Chinese, Polish, Italian, and Hebrew which are source languages with large, well-documented English-language training corpora available to model builders generally. Outside that one direction, DeepSeek's advantage holds almost everywhere: out of English, and between non-English language pairs alike.
What this rules out is treating either model as a universal default. A team translating product listings from Spanish into six languages and expecting the same performance ranking they saw translating a Chinese support ticket into English would be applying the wrong lesson from the wrong direction which is the same asymmetry that shows up in MachineTranslation.com's Spanish-to-English model breakdown, where the leading models aren't the same ones that lead in the reverse direction.
Are Qwen and DeepSeek free and open-source?
Licensing splits differently for each. DeepSeek licenses both V4 Pro and V4 Flash under MIT, one of the most permissive open-source terms available, so both are free to self-host without restriction. Qwen is split: Qwen3.8-27B ships under Apache 2.0 and is free to self-host, but the flagship Qwen3.8-Max stays closed, API-only, and under Alibaba's own custom license.
Practically, that means a fully open-weight, MIT-licensed option exists on the DeepSeek side at both quality tiers. On the Qwen side, going open-weight means giving up the flagship model.
What do Qwen and DeepSeek cost to run at scale?
Following DeepSeek's permanent price cut in May 2026, its current published API rates are $0.435 per million input tokens (cache miss) and $0.87 per million output tokens for V4 Pro, with V4 Flash priced lower for its latency-optimized tier.
For teams self-hosting either model instead of using a hosted API, the cost comparison shifts entirely to GPU infrastructure and becomes a function of parameter count and active-parameter efficiency rather than a per-token rate.
Is either model safe enough for legal, medical, or regulated content?
Neither model publishes translation-specific safety certifications, and general-purpose safety benchmarks don't test for the failure modes that matter in regulated content: a mistranslated dosage, a shifted liability clause, an inconsistent legal term. MachineTranslation.com's own testing has found exactly this kind of divergence between models on legal and medical language, including cases where models used different legal terms with different scopes despite both scoring well on general quality metrics.
For contracts, immigration documents, or clinical content, that's the case for pairing either model's output with a human verification step rather than trusting a single AI output at face value, regardless of which model produced it.
What does this mean if you're localizing into many languages at once?
A comparison built on one language pair tells you almost nothing about pair number forty. The into-English/out-of-English split documented here held across a 98-pair sample specifically because it was tested at that scale: a single English-to-Spanish test, which is what most Qwen vs DeepSeek comparisons run, would have shown DeepSeek comfortably ahead and said nothing about what happens once Tamil, Polish, or Hebrew enter the pipeline.
That's the practical argument for not locking a large localization program to one model's output by default. MachineTranslation.com runs both Qwen and DeepSeek, along with more than 20 other models, on every translation and surfaces the version those models most agree on, so a 68-language rollout isn't riding on whichever model happened to win the one pair someone tested first. You can see exactly which models agreed or diverged on any given translation in the per-translation model breakdown the platform shows for every result.
Every translation gets checked against a wider range of models than either Qwen or DeepSeek alone can offer, which is the direct answer to what happens once your content stops moving in just one direction.
Frequently asked questions
1. Is Qwen or DeepSeek better for translation?
Across 98 language pairs tested on identical source text, DeepSeek scored higher in 83 of them. Qwen's wins cluster in one specific direction: translating into English, where it wins about a third of the time. In every other direction, DeepSeek wins more than 90% of the time.
2. Is Qwen free to use?
Qwen3.8-27B is open-weight under Apache 2.0 and free to self-host. The flagship Qwen3.8-Max is closed and only available through Alibaba Cloud's paid API.
3. Is DeepSeek free to use?
Yes. Both DeepSeek V4 Pro and V4 Flash ship with MIT-licensed open weights, so you can self-host either one at no licensing cost. DeepSeek also offers a paid API for teams that don't want to manage their own infrastructure.
4. Which is faster, Qwen or DeepSeek?
DeepSeek V4 Flash is built specifically for low latency, with 13 billion active parameters per token versus V4 Pro's 49 billion. Qwen's equivalent lighter option, Qwen3.8-27B, is dense rather than mixture-of-experts, which generally makes it slower per token at comparable quality.
5. Can I use Qwen and DeepSeek together for translation?
Yes. MachineTranslation.com runs both models, plus over 20 others, on every translation and surfaces the version they most agree on, so you're not stuck picking one model and hoping it's the stronger choice for that specific language pair.
6. What's the difference between Qwen and DeepSeek's licensing?
DeepSeek licenses both V4 variants under MIT, one of the most permissive open-source licenses available. Qwen splits its lineup: smaller models like Qwen3.8-27B ship under Apache 2.0, but the flagship Qwen3.8-Max stays closed under a custom license.
By Rachelle Garcia
Connect on LinkedInRachelle leads product and AI at Tomedes, where she runs the experiments that turn internal data into better translation experiences. She writes about what actually happens when you build AI products such as MachineTranslation.com — the numbers, the surprises, and the parts that don't go to plan.
Share:


