November 5, 2026
Qwen vs Gemini for translation and why direction matters
You have two models and a list of language pairs, and you need to decide which model to trust with the project. Most Qwen vs Gemini comparisons answer with one overall score. I think one score hides what decides the outcome, which is the direction of the translation.
I work on how we test the models that run on MachineTranslation.com, so I can compare Qwen and Gemini on 98 language pairs scored on identical text. Gemini scored higher in 68 of those pairs and Qwen in 29, and the average gap is 0.08 points out of 10. The totals alone do not tell you which model to pick for Urdu to English or for English to Haitian Creole.
This article shows where the two models are close and where each one leads. It also says what I cannot tell you yet. My data ends on August 8, 2026, before Google announced Gemini 4 in October, so it describes the earlier versions of both models.
Key takeaways
- Across 98 language pairs scored on identical text (July 12 to August 8, 2026), Gemini scored higher in 68 pairs, Qwen in 29, and one pair tied.
- The average gap is small, 9.06 for Gemini against 8.98 for Qwen, and 60 of the 98 pairs sit within 0.1 points.
- Translating into English, Qwen leads by more than 0.1 points in 7 of 27 pairs and Gemini in 3; the other 17 are within 0.1 points.
- Translating out of English, Gemini leads by more than 0.1 points in 13 of 29 pairs and Qwen in none.
- The data ends before Google announced Gemini 4 in October 2026, so it describes the earlier Gemini versions and needs a fresh run before anyone treats it as current.
Is Qwen or Gemini better for translation?
It depends on the direction, because the two models are close when the target language is English and Gemini scores higher in most other pairs. Across all 98 pairs, Gemini scored higher in 68. In MachineTranslation.com's scores from July 12 to August 8, 2026, Gemini averaged 9.06 out of 10 and Qwen 8.98, an average gap of 0.08 points.
The panel counts only segments where ChatGPT, Claude, DeepSeek, Gemini, and Qwen all received a real score, so every model is judged on identical source text. Each language pair has at least 30 segments. I use this panel because it removes a common error, which is comparing models on different text.
By count, Gemini is ahead in 68 pairs (69%), Qwen in 29 (30%), and one pair is tied. Count alone overstates the gap, because 60 of the 98 pairs are within 0.1 points. The next sections split the results by direction and by margin.
Which translation directions favor each model?
Gemini leads when English is the source language or when neither language is English, and Qwen is level with it or ahead when English is the target. Out of English, Gemini leads by more than 0.1 points in 13 of 29 pairs and Qwen in none. Into English, Qwen leads by that margin in 7 of 27 pairs and Gemini in 3.
| Direction | Pairs | Gemini ahead by more than 0.1 | Within 0.1 points | Qwen ahead by more than 0.1 | Average gap |
|---|---|---|---|---|---|
| Into English | 27 | 3 | 17 | 7 | Qwen +0.04 |
| Out of English | 29 | 13 | 16 | 0 | Gemini +0.16 |
| Neither side English | 42 | 14 | 27 | 1 | Gemini +0.13 |
Into English, 17 of 27 pairs are within 0.1 points, Qwen leads in 7, and Gemini leads in 3. Out of English, 16 of 29 pairs are within 0.1 points, Gemini leads in 13, and Qwen leads in none. Where neither language is English, 27 of 42 are within 0.1 points, Gemini leads in 14, and Qwen leads in 1.
Qwen is within 0.1 points of Gemini or ahead in 24 of the 27 pairs into English. Averaged by direction, Qwen is ahead by about 0.04 points into English, while Gemini is ahead by about 0.16 points out of English and 0.13 points between two non-English languages.
I do not know why the split appears, and this data cannot tell me. One explanation I would test first is the mix of training text behind each model, but I have not run that test. Qwen shows a similar shape against ChatGPT. On the same panel, our Qwen vs ChatGPT comparison found the two close to even into English, with ChatGPT ahead in 89% of the other pairs.
Which language pairs show the biggest gaps?
The largest gaps favor Gemini. It leads by 0.51 to 0.95 points on Russian to Kazakh, English to Haitian Creole, English to Tagalog, Spanish to Greek, and Arabic to Persian. Qwen's largest leads are smaller, between 0.15 and 0.26 points, and four of its top five are pairs into English.
| Language pair | Gemini score | Qwen score | Gap |
|---|---|---|---|
| Russian to Kazakh | 9.27 | 8.32 | Gemini +0.95 |
| English to Haitian Creole | 9.19 | 8.27 | Gemini +0.92 |
| English to Tagalog | 9.14 | 8.43 | Gemini +0.70 |
| Spanish to Greek | 8.90 | 8.33 | Gemini +0.57 |
| Arabic to Persian | 8.84 | 8.34 | Gemini +0.51 |
| Urdu to English | 8.56 | 8.81 | Qwen +0.26 |
| Chinese to English | 9.00 | 9.19 | Qwen +0.19 |
| Swedish to English | 8.29 | 8.46 | Qwen +0.16 |
| Chinese to Indonesian | 9.03 | 9.19 | Qwen +0.16 |
| Burmese to English | 8.94 | 9.09 | Qwen +0.15 |
I would not treat these as final rankings. The two largest gaps, Russian to Kazakh and English to Haitian Creole, rest on smaller samples than the median pair. English to Tagalog, Spanish to Greek, and Arabic to Persian rest on larger ones, so I would trust those three more. I would re-test the two thin-sample gaps before relying on them.
What does a gap of 0.1 points mean?
In my view, a gap under 0.1 points is too small to call a winner. Of the 98 pairs, 60 fall inside that margin, and each pair is scored on a limited number of segments. The 0.1 line is my own working threshold, and I have not run a significance test on these pairs.
A score also misses some differences. In our common phrase tests, we ran "sorry" in Arabic through 22 AI models. Gemini and Qwen both chose the casual آسف. ChatGPT and the combined result chose the formal عذرًا. Every model scored 9.5, so the two words differ in register and the score did not move.
That is why I read the margin and the register examples together. A small gap with a visible register difference needs a human decision. A large gap on a thin sample needs a re-test.
Do Qwen and Gemini make different kinds of mistakes?
Yes, because in our 2026 World Cup quote test both models made at least one choice that the other models did not, and the scores barely moved. Gemini translated a Mbappé phrase as "with each game" and rendered a Wirtz quote word for word, while Qwen gave a different reading of a Scaloni quote. The scores for these cases ran from 9.2 to 9.5.
The details come from our World Cup quote test. On Mbappé's quote about looking ahead, the other models kept "match" while Gemini wrote "with each game", a small slip in register that scored 9.4. On a Wirtz quote, Gemini translated a phrase word for word and changed the meaning, also at 9.4. On Scaloni's quote, most models converged on one reading while Qwen wrote "that is what matters" and scored 9.4. On Mbappé's tactical quote, Claude and DeepSeek chose British football English while Gemini, Qwen, and the others chose American English, and Qwen scored 9.2, lower than the rest.
I read these as small habits. Gemini's examples are about register and literal phrasing. Qwen's are about which reading of a line to choose. Four examples are too few to call a pattern, but they show the kind of difference a single score hides.
Which Qwen model is best for translation?
I cannot say from our data, because MachineTranslation.com's scores treat Qwen as one model without a version tag. Alibaba's Qwen3.8 family reached Hugging Face in August 2026, so several versions now exist, and the scores in this article do not separate them.
I would like to split this by version, and I cannot yet. The platform-level number may average over more than one Qwen version that ran in the window. If you are choosing between Qwen versions for a project, I would compare them on a sample of your own text.
What are some alternatives to Gemini for translation?
ChatGPT, Claude, DeepSeek, Qwen, Grok, and Mistral AI all run on MachineTranslation.com, and the right alternative depends on the pair. In our July 12 to August 8, 2026 scores, Qwen is within 0.1 points of Gemini or ahead in 24 of 27 pairs into English. Our Mistral AI French scores show its French to English average sitting 0.40 points above Gemini's.
If your alternative is ChatGPT, the answer also splits by pair. In our published Spanish to English breakdown, Gemini won 31% of segments and ChatGPT won 21%. On French, neither model wins both directions. Because the choice changes with the pair, MachineTranslation.com does not pick one alternative. It runs them together.
My suggestion is to start from the pair and the direction, and then look at which alternative fits.
How does MachineTranslation.com show where Qwen and Gemini disagree?
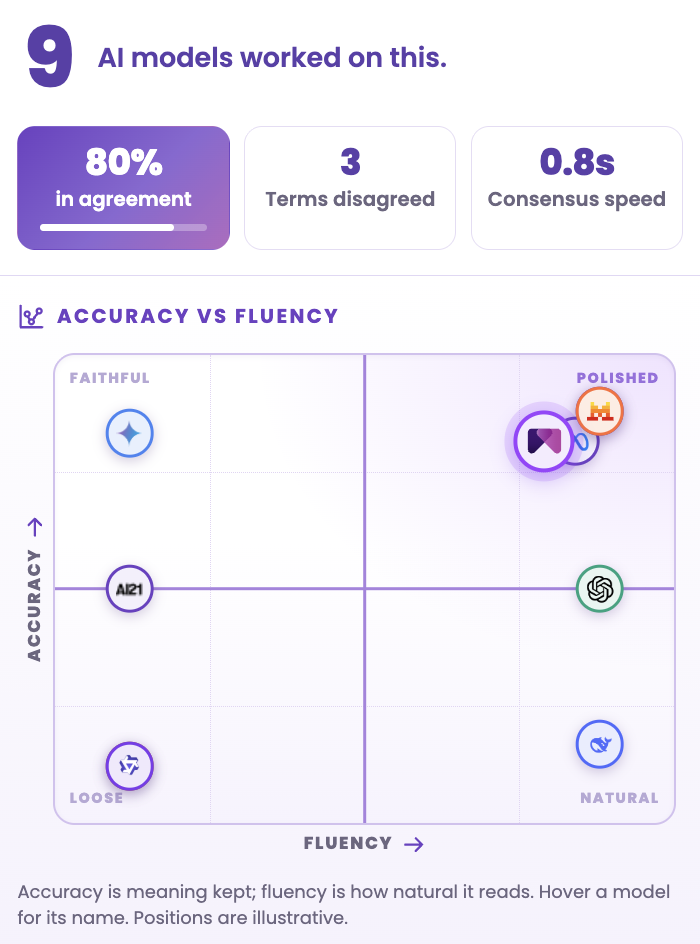
MachineTranslation.com runs both models on every translation and shows where the models agree and where they split. The agreement panel reports how many AI models worked on the text, the share in agreement, how many terms were disputed, and how fast the consensus formed.
How current are these results?
These results cover July 12 to August 8, 2026, so they describe the Gemini and Qwen versions running then. Google announced Gemini 4 in October 2026. Alibaba's Qwen3.8 family arrived in August 2026. My recommendation is to rerun the panel before relying on these numbers for a new project.
I expect the method of comparing identical text with a margin for noise to hold up. I expect the size of the gaps to change. I would treat any pair where the leader flips on a new run as a sign that the earlier gap was within noise.
How would I choose between Qwen and Gemini for a project?
My take is to choose by pair and direction and to avoid choosing once for a whole project. In practice that means treating a gap under 0.1 points as a tie and expecting the leading model to change between pairs. This is the order I would follow.
- List every language pair in the project and mark its direction.
- Check the gap for each pair in this article. Treat a gap under 0.1 points as a tie.
- Where the gap is larger, start with the leading model and test a sample of your own text.
- If your content moves in both directions, expect the leader to change between pairs.
- Check again when either model releases a new version.
Both models run alongside 20 others on every translation in MachineTranslation.com. The version most of them agree on is returned, so the choice does not have to be made once for the whole project. The full set of model results is in our model comparison testing.
Frequently asked questions
1. Is Qwen or Gemini better for translation?
It depends on the direction, because Qwen is within 0.1 points of Gemini or ahead in 24 of 27 pairs into English. Gemini still scored higher in 68 of 98 pairs in MachineTranslation.com's July 12 to August 8, 2026 scores. The average gap is 0.08 points out of 10, so I would choose by pair.
2. Which Qwen model is best for translation?
I cannot say from our data, because MachineTranslation.com's scores treat Qwen as one model without a version tag. Alibaba's Qwen3.8 family reached Hugging Face in August 2026, so several versions now exist. Until the scores separate them, I would compare versions on a sample of your own text before choosing one for a project.
3. What are some alternatives to Gemini for translation?
ChatGPT, Claude, DeepSeek, Qwen, Grok, and Mistral AI all run on MachineTranslation.com. In our July 12 to August 8, 2026 scores, Qwen is within 0.1 points of Gemini or ahead in 24 of 27 pairs into English. Mistral AI's French to English average sat 0.40 points above Gemini's. The right alternative depends on the pair.
4. Is Gemini better than ChatGPT for translation?
It depends on the language pair, because no single AI model wins everywhere. In our published Spanish to English breakdown, Gemini won 31% of segments and ChatGPT won 21%. On French, neither model wins both directions. I would check the pair and the direction you need before choosing between them.
5. Is Gemini accurate for translation?
Yes, because Gemini averaged 9.06 out of 10 across 98 language pairs in MachineTranslation.com's July 12 to August 8, 2026 scores. Accuracy still varies by pair. Its lead is widest out of English, and Qwen is ahead of it by more than 0.1 points on 7 of 27 pairs into English.
By Rachelle Garcia
Connect on LinkedInRachelle leads product and AI at Tomedes, where she runs the experiments that turn internal data into better translation experiences. She writes about what actually happens when you build AI products such as MachineTranslation.com — the numbers, the surprises, and the parts that don't go to plan.
Share:


